MCP RCE Debate: Treat Agent Plugins Like Executable Code
OX Security found a remote code execution design flaw in MCP's official SDKs: 10 CVEs, 30+ disclosures, 7,000+ exposed servers. Treat MCP servers as code.
OX Security’s April 2026 research found a remote code execution design flaw in the official Model Context Protocol SDKs for Python, TypeScript, Java and Rust: 10 critical or high CVEs, more than 30 coordinated disclosures, and over 7,000 publicly exposed servers. The conclusion developers reached is simpler than the CVE list. An MCP server is executable code, not a bookmark.
Updated September 2026: the MCP specification’s own security best practices page now carries a “Local MCP Server Compromise” section requiring clients to display the exact command, untruncated, before a one-click install. The posture recommended below is unchanged.
The research was published on April 15, 2026 and covered by The Hacker News, Tom’s Hardware, TechRadar and VentureBeat. OX framed the finding as architecture rather than a coding slip:
This is not a traditional coding error. It is an architectural design decision baked into Anthropic’s official MCP SDKs.
— OX Security, April 2026
The numbers are attention-grabbing. The debate that followed is the more useful artifact, because it is where developers converged on a working mental model for every agent capability they install.
Key Figures
| Figure | What it measures | Source |
|---|---|---|
| 150 million | Downloads of affected MCP SDK packages | OX Security, April 2026 |
| 200,000 | Upper-bound estimate of vulnerable MCP instances | OX Security |
| 7,000 | Publicly exposed MCP servers located | OX Security |
| 10 | Critical or high CVEs issued | OX Security |
| 30 | Coordinated disclosure processes opened | OX Security |
| 6 | Live production platforms compromised during research | OX Security |
| 9 of 11 | MCP registries successfully poisoned in testing | OX Security |
| 4 | Official SDK languages affected | OX Security |
| 9 | MCP risk categories catalogued by OWASP | OWASP MCP Security Cheat Sheet |
| 12 | Best-practice control sections in the same cheat sheet | OWASP |
More on the controls these figures point at: SkillSafe MCP security.
How the STDIO Flaw Works
The mechanism is short enough to state in one sentence: a value that an attacker can influence reaches the MCP client’s server configuration, the client turns that configuration into StdioServerParameters, and the SDK spawns a child process from it without a validation step in between.
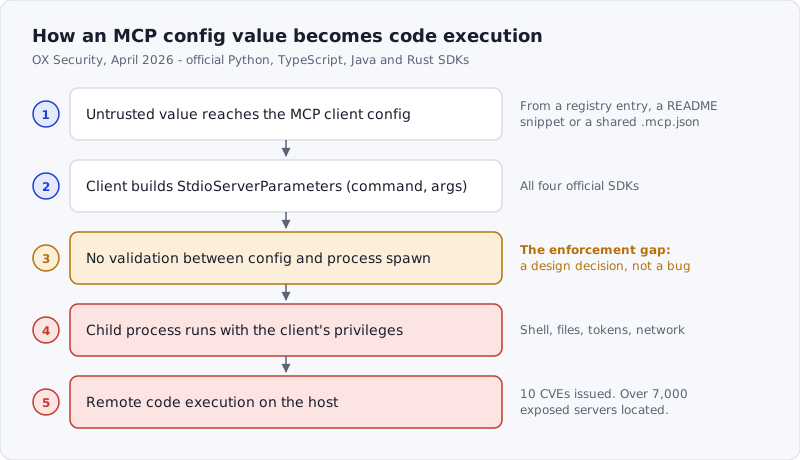 Figure: the STDIO path from an untrusted configuration value to code execution. The gap OX Security identified is the missing validation between config and spawn, not a mistake inside any one server.
What makes it a supply-chain problem rather than a single-vendor bug is the distribution path. The configuration value does not have to come from the user. It can come from a registry entry, a README snippet, a shared .mcp.json, or a marketplace listing. OX reported poisoning 9 of 11 MCP registries it tested, which is the part that should worry anyone who installs servers by copying a snippet.
The MCP specification now documents this class directly. Its security page lists arbitrary code execution, command obfuscation and data exfiltration as risks of local servers, and gives a blunt example of what a malicious startup command looks like: a package install chained to a curl upload of ~/.ssh/id_rsa.
The Argument People Are Having
MCP is often described as a standard way for AI agents to connect to tools, data sources, and external systems. That framing is true, but incomplete. A connector that reads documentation is one thing. A connector that can run shell commands, access local files, query internal systems, or call cloud APIs is something else entirely.
The disagreement across Hacker News, Reddit’s webdev community and Claude user discussions is not whether arbitrary command execution is dangerous. Everyone agrees it is. The disagreement is where responsibility should sit.
One side argues that MCP’s STDIO behavior is a design flaw. If configuration values can flow into local process execution before meaningful validation, then the protocol and reference SDKs create an unsafe default. In this view, downstream frameworks inherit risk even when their developers believe they are simply adding agent tooling.
The other side argues that running an MCP server is already equivalent to running software. If you install untrusted code, the protocol is not the root problem. The same logic applies to npm packages, PyPI packages, VS Code extensions, shell scripts, and Docker containers. The real failure is treating plugin installation as if it were a low-risk connection step.
Both sides are pointing at real issues.
MCP does make tool integration easier, and that is valuable. But making tool integration easy also makes tool distribution easier. Once an agent can discover and invoke external capabilities, the security problem shifts from “can this model answer correctly?” to “who controls the capabilities this model is allowed to use?”
Plugins Are Supply Chain
The practical lesson from the MCP debate is that agent plugins belong in the software supply chain, not in a separate category of “AI configuration.”
When a developer installs a plugin, connector, MCP server, or skill, they are not just adding instructions. They are changing the operational boundary of the agent. The agent may now be able to read files, create tickets, modify databases, send messages, deploy code, query secrets, or open network connections.
That means the security questions look familiar:
- Who published this capability?
- Has the source changed since it was reviewed?
- What permissions does it request?
- Can it execute code?
- Can it read credentials?
- Can it send data outside the machine?
- Is there a review process before updates roll out?
- Can a compromised publisher or server operator change behavior after trust is established?
These are dependency-management questions. The fact that the consumer is an AI agent rather than a human developer does not make them less important.
In fact, it makes them more important. A human running a suspicious command may hesitate. An agent with tool access may simply execute the next plausible step in the workflow.
OWASP reached the same conclusion independently. Its MCP Security Cheat Sheet catalogues 9 risk categories, and 3 of them are pure supply chain: rug pull attacks, supply chain attacks, and consent and installation security. Its recommended control for rug pulls is the one packaging ecosystems learned decades ago: pin tool definitions to cryptographic hashes and alert on any change. More background on that pattern: supply-chain posts.
The Skill Layer Has the Same Shape
At SkillSafe, we spend most of our time thinking about AI skills: reusable instruction bundles that teach agents how to perform specific tasks. Skills are not the same thing as MCP servers, but they share the same supply-chain shape.
A skill changes agent behavior by shaping intent. A plugin or MCP server changes agent behavior by expanding capability. One tells the agent what to do; the other gives it more ways to act.
Attackers can abuse both layers.
We saw that with malicious AI skill campaigns like ClawHavoc, where apparently useful skills carried credential-stealing behavior. We saw it again in MCP tool poisoning, where hidden tool metadata can influence model behavior in ways users never see. We have seen the broader software version of the same pattern in trusted package compromises and the LiteLLM supply-chain attack.
The mechanism changes. The target does not. Attackers want an agent with access to a useful environment.
That environment might contain source code, SSH keys, API tokens, customer data, deployment credentials, GitHub permissions, CI secrets, Slack workspaces, Notion docs, or cloud infrastructure. Skills and plugins are valuable because they let agents operate inside that environment. They are risky for the same reason.
Why the Discussions Matter
The Hacker News thread on MCP RCE risk is useful because it pushes past a shallow “MCP bad” conclusion. Several commenters make the package analogy explicitly: connecting to arbitrary MCP servers should not be treated like visiting a website. It is more like installing a package or extension that runs with local privileges.
That is the right mental model.
The Reddit discussion in r/webdev is useful for a different reason. It captures the frustration many developers feel when a tool marketed as a standard appears to place security burden on every downstream implementer. Developers do not want every new AI integration to require a protocol-level threat-modeling exercise.
The Claude user discussions are more operational. People ask what they should do with their existing MCP configs, whether local STDIO servers are safe, and how much trust they should place in servers installed from public registries.
Those are the questions teams should be asking before rolling agent tooling into production.
The best discussions are not arguing about whether agents should have tools. They are arguing about the right default posture for tool access. That is a much more productive conversation.
The Default Posture Should Be Suspicion
If agent plugins are supply-chain artifacts, then the default posture should match supply-chain security — the same ground our 12-check MCP security checklist covers phase by phase:
Treat unknown plugins as untrusted code. Do not install an MCP server, connector, or skill from a random source because it has a useful name. Review where it came from, what it does, and who maintains it.
Separate low-risk and high-risk capabilities. A documentation lookup tool and a filesystem writer should not be treated the same way. Tools with shell, filesystem, credential, network, or deployment access need stricter approval and monitoring.
Require human approval for privileged actions. Human-in-the-loop approval is annoying until it prevents a tool chain from reading secrets or pushing code. High-friction review belongs around high-impact actions.
Scan static artifacts before installation. Skills, plugin manifests, server code, and tool descriptions can all carry suspicious patterns. A scan report is not perfect, but static analysis catches obvious credential access, obfuscation, exfiltration, and prompt-injection patterns before an agent consumes them.
Monitor runtime behavior. Static review does not catch a remote server that changes its tool metadata after installation. Runtime logging, permission boundaries, and update review are necessary for live connectors.
Pin versions where possible. A tool that was safe last month may not be safe after an update, a maintainer compromise, or a server-side change. Pinning and review slow down rug pulls.
Build allowlists, not open plugin free-for-alls. Enterprise agent deployments should have approved catalogs. The goal is not to block tool use; it is to make tool use intentional.
Those seven rules collapse into four points where a decision can actually be enforced.
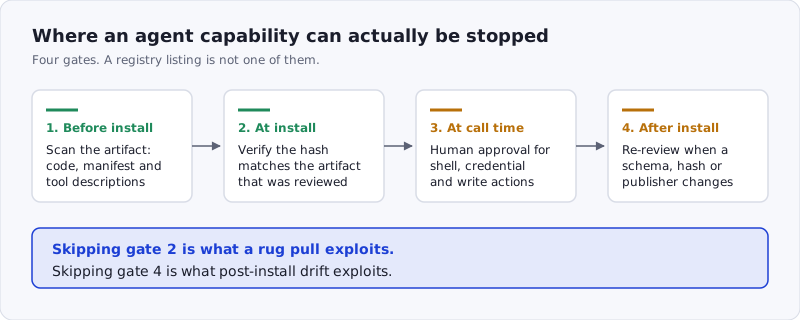 Figure: a registry listing is not an enforcement point. Skipping gate 2 is what a rug pull exploits; skipping gate 4 is what post-install drift exploits.
Where Skills, Plugins, and MCP Go From Here
The agent ecosystem is moving toward three layers:
Skills encode reusable workflow knowledge. They tell an agent how a team wants work done. Browse what that looks like in practice in the skill registry.
Plugins, connectors, and MCP servers expose data and actions. They let an agent reach outside the model into real systems.
Agent-to-agent protocols such as A2A turn agents themselves into callable capabilities. They let one agent delegate work to another.
Each layer adds power. Each layer also adds supply-chain risk.
That does not mean teams should avoid agent tooling. It means agent tooling needs the same seriousness we already apply to package registries, CI/CD systems, browser extensions, OAuth apps, and cloud IAM.
The MCP security debate is a useful reset because it forces the industry to drop the “just connect a tool” language. Connecting a tool is a security decision. Installing a skill is a security decision. Letting an agent act across your development environment is a security decision.
Once teams accept that, the path forward is not mysterious. Verify publishers. Scan artifacts. Restrict permissions. Require approval for dangerous actions. Keep audit logs. Review updates. Treat agent capabilities as part of the software supply chain.
Frequently Asked Questions
Are MCP servers a security risk?
Yes, in the same way any installed package is. OX Security’s April 2026 audit issued 10 critical or high CVEs across the official Python, TypeScript, Java and Rust SDKs and located more than 7,000 exposed servers. A local MCP server runs with the client’s privileges, so the risk is code execution, not just bad answers.
How do you secure MCP servers?
Follow the two authoritative checklists. The MCP specification’s security best practices require per-client consent, exact redirect-URI matching, and no token passthrough. The OWASP MCP Security Cheat Sheet adds 12 control sections, of which sandboxing, hash-pinned tool definitions, and human-in-the-loop approval for sensitive actions matter most.
Is MCP safe to use in production?
MCP is safe to the degree you constrain it. The protocol has no built-in authority to stop a malicious server, which is why the specification states that servers must not accept tokens that were not issued for them. Treat each server as a dependency with a publisher, a version, a hash, and a permission set.
What are the best practices for MCP authentication?
Audience-validate every token, never forward a client token to a downstream API, and store per-client consent server-side before any third-party authorization redirect. The specification also requires cryptographically random, single-use state values with short expiry, and exact-string redirect-URI matching rather than wildcard patterns.
AI agents are becoming useful because they can do real work. The security model has to start from the same premise.
Real work has real blast radius.